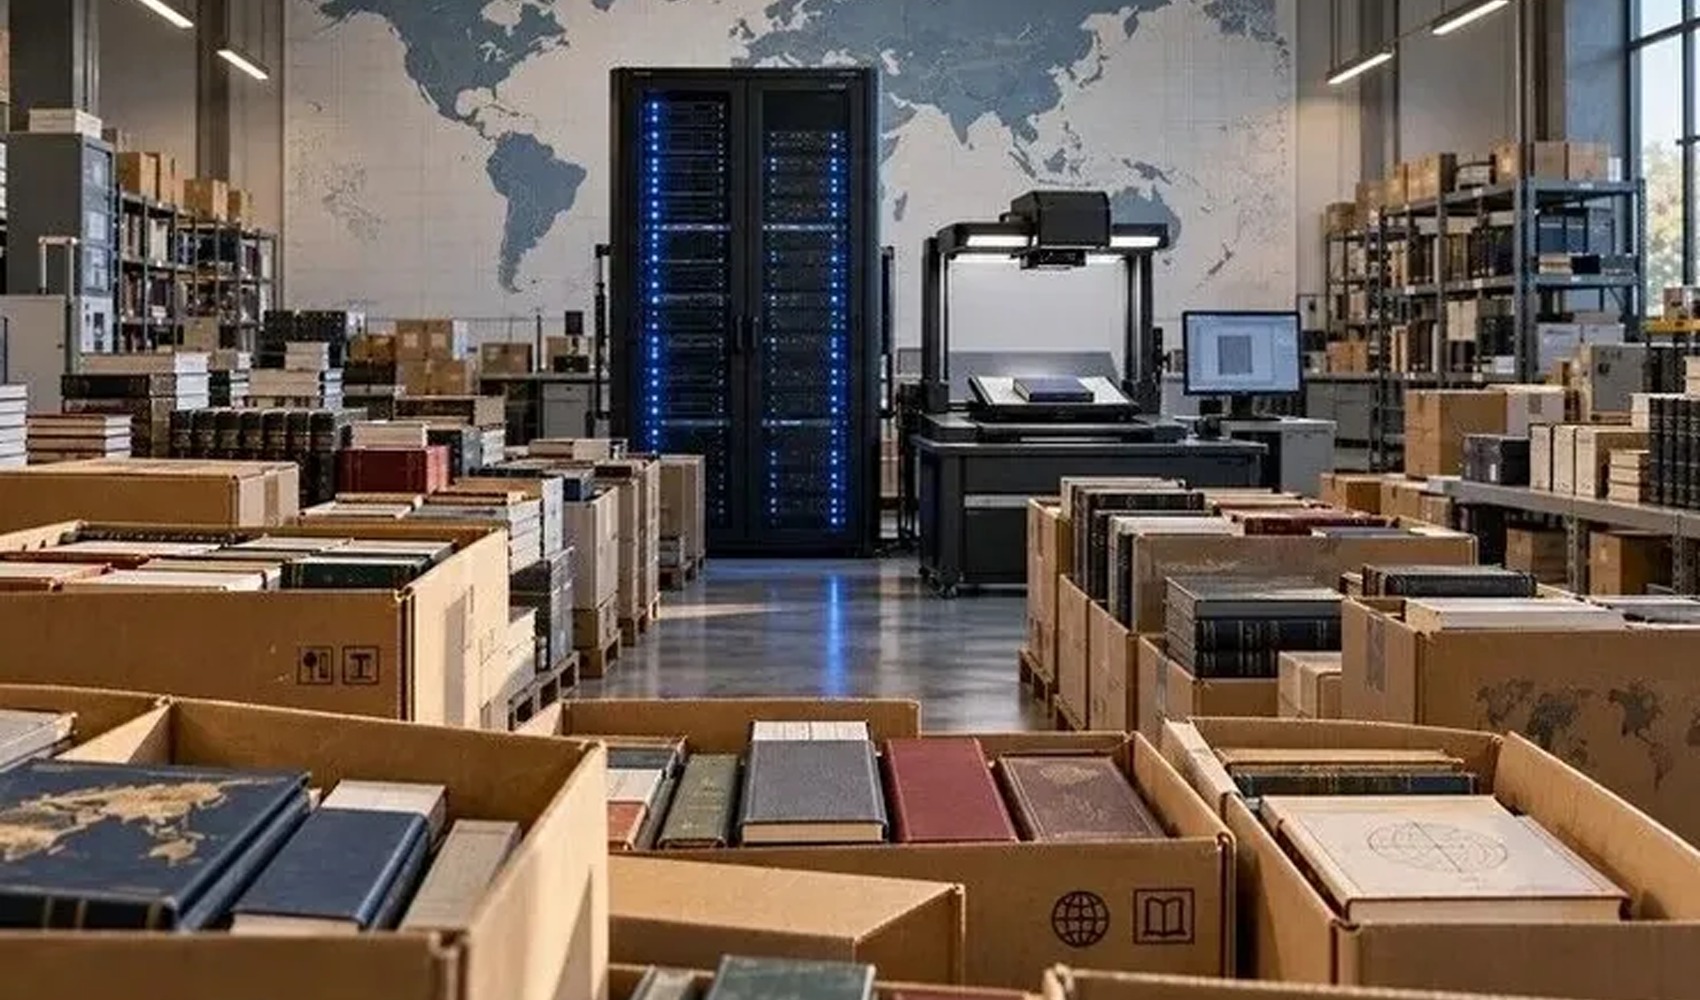
The attempts by artificial intelligence companies to convert printed and digital books into large-scale datasets have brought the debate over copyright and data usage back to the forefront of the publishing industry.
Prof. Dr. Selçuk Beşir Demir announced that they had rejected a request from a global firm for access to 17 thousand academic books. Demir emphasized that such requests cannot be viewed merely as a technical data collection activity, noting that they could have serious consequences for publishers, authors, and academic production.
Describing the process as a "war between Silicon Valley and the cellulose industry," Demir stated that copyright and permission mechanisms must be protected for content used to train artificial intelligence models.
The primary concern in the publishing world is that the mass scanning of books for use in training artificial intelligence systems will weaken the income, control, and citation rights of authors. It is stated that this situation could increase the risk of "data exploitation" and market contraction, particularly for Turkish academic publications.
Demir called for the establishment of a stronger protection framework against copyright violations, while also expressing that domestic content production must be secured during the digital transformation process of academic publishing.
News Source: 12punto