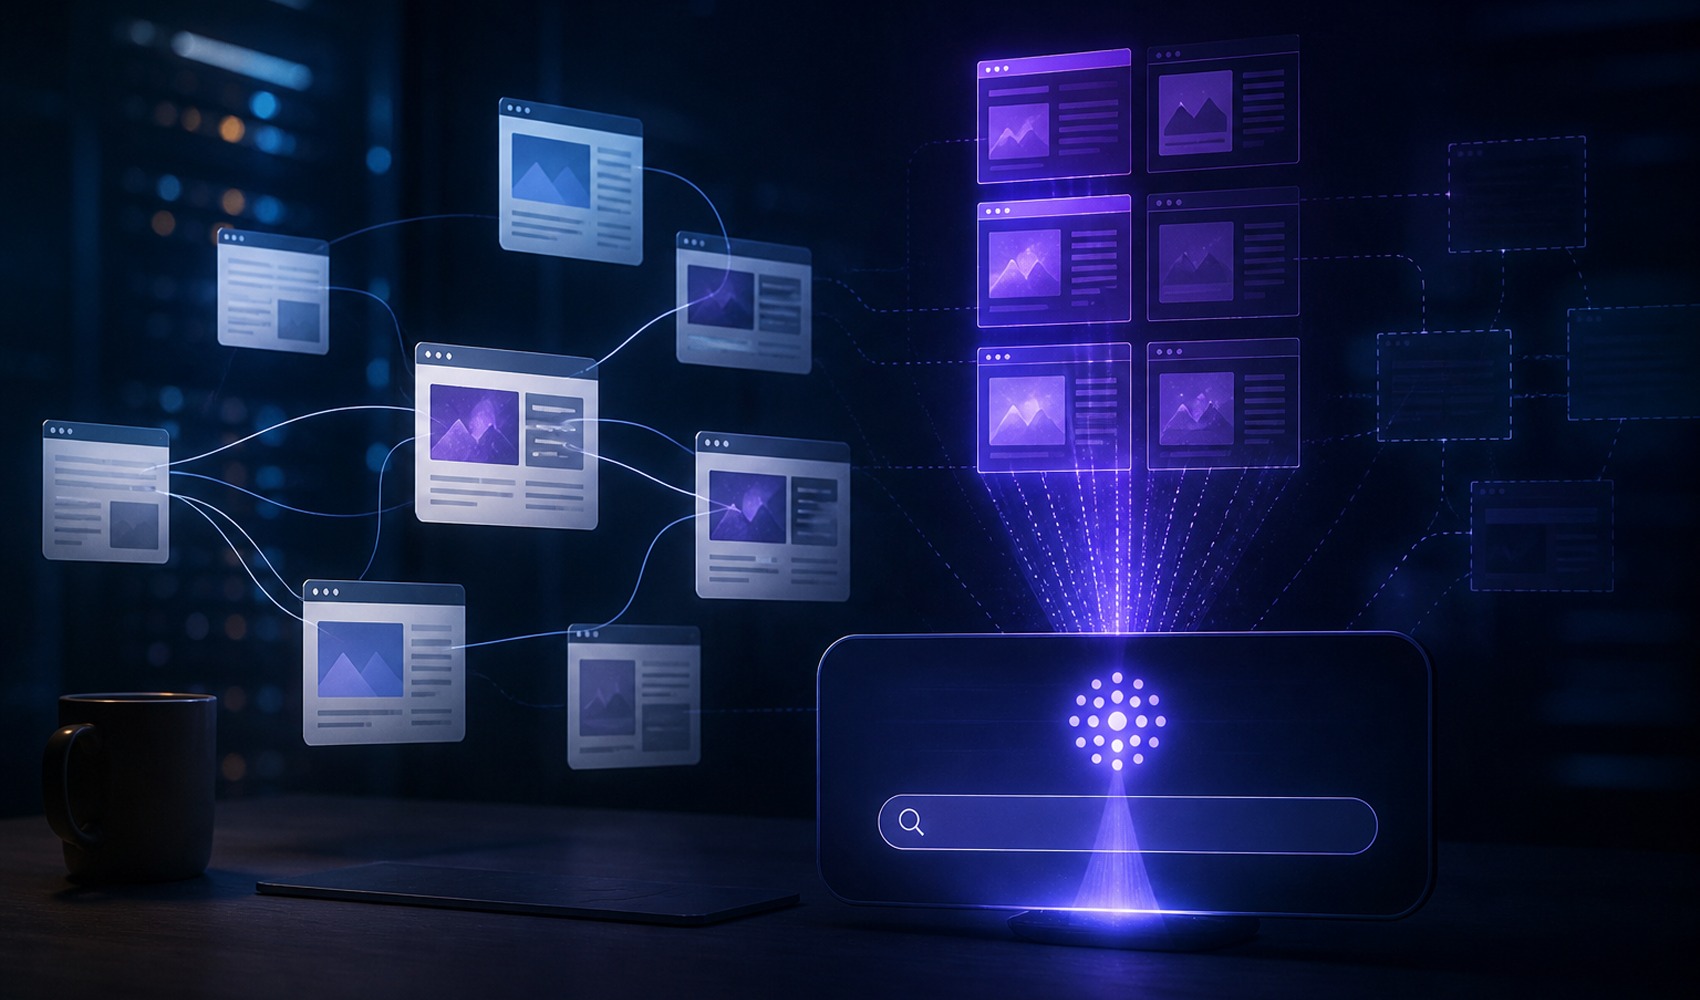
The project launched by Cloudflare and OpenAI in July aims to bring web pages that classic search engines might overlook into ChatGPT's search index. At the heart of the approach is leveraging signals obtained from real user traffic on the Cloudflare network instead of tracking links between sites.
Traditional web crawlers mostly find new pages by following links provided from other pages. While this method covers the vast majority of visible content on the internet, some pages that do not receive links can remain outside of search results. For example, a product's user manual, a small business's menu, or local content that answers a specific need may not be discovered if they are not pointed to by other sites.
The new method focuses on traffic patterns related to pages that users actually visit. Signals coming from Cloudflare's network help identify hundreds of millions of pages that traditional crawlers cannot reach. Thus, it is aimed at creating a broader and more diverse content index for ChatGPT search.
MORE EFFICIENT CRAWLING WITH TRAFFIC SIGNALS
One of the potential benefits of this model is reducing the resource usage of automated crawlers. Crawlers can occasionally send requests to pages that no longer exist, duplicate content, or low-value addresses. Utilizing traffic signals can contribute to more efficient use of crawling resources by showing which pages are actually visited.
The project also draws attention in terms of security assessments. A single problematic page on a domain does not necessarily mean the entire site is malicious. Performing assessments at the page level could help preserve the search visibility of the rest of the site's content. However, details regarding how such distinctions are technically implemented within the project need to be clarified further.
Adding more pages to the index could mean a new discovery channel for publishers and site owners. However, being indexed does not automatically mean gaining more visitors. Traffic directed to websites via ChatGPT, click-through rates, and how AI crawlers' access to content will be managed are among the topics that will determine the project's impact.
News Source: 12punto